<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://svivek.com//writing/feed.xml" rel="self" type="application/atom+xml" /><link href="https://svivek.com//" rel="alternate" type="text/html" /><updated>2026-08-26T00:01:24-06:00</updated><id>https://svivek.com//writing/feed.xml</id><title type="html">Vivek Srikumar | Writing</title><subtitle>Vivek Srikumar&apos;s website</subtitle><entry><title type="html">Why do I read research papers?</title><link href="https://svivek.com//writing/2026-08-18-why-i-read-papers.html" rel="alternate" type="text/html" title="Why do I read research papers?" /><published>2026-08-18T00:00:00-06:00</published><updated>2026-08-18T00:00:00-06:00</updated><id>https://svivek.com//writing/why-i-read-papers</id><content type="html" xml:base="https://svivek.com//writing/2026-08-18-why-i-read-papers.html"><![CDATA[<p>The old wisdom was that a part of a researcher’s job is to read papers. The new
wisdom questions whether a researcher really needs to read papers. It is easy to
upload an article to Claude or ChatGPT to get a summary of the key
contributions. Armed with this knowledge, a researcher can focus on the problems
they care about.</p>

<p>The goal of doing research is, after all, to advance our understanding of
something out there. AI assistants can accelerate this process. We would not
need to read every paper written on the topic. We can just find papers relevant
to our work (perhaps, with an assistant), feed them into the assistant, and ask
it to digest them. This way, instead of expending the time to read the papers,
we can just consume the pre-cooked digest.</p>

<p>I love the vision. But I still like reading papers.</p>

<p>Our models are excellent at synthesizing the key points from text. But I want
more than a summary of the information in the paper. I want an <em>interpretation</em> of
the paper. To be more precise, I want <em>my interpretation</em> of the paper. Let me
elaborate.</p>

<p>Understanding is not the same as interpretation. Understanding a paper,
especially in a technical area, focuses on the core contributions and findings.
Barring unusual circumstances, people would generally agree on these. If a paper
in widget-ology shows that widgets of type 1 are more energy efficient than
widgets of type 2, then that represents the facts of the case. A good summary of
the paper would say so.</p>

<p>When ChatGPT synthesizes a paper, without instructions to the contrary, it
reaches for a summary. It can even dive deeper into the technical details than
the paper itself does. Is the summary neutral though? Facts can be seen through
a certain lens. The widget-ologist who architected type 1 may focus on the
headline result, while the one who made type 2 might quibble about the
evaluation quality. The popular media might focus on the money wasted on widget
research. A mathematician may realize that they can analytically explain the
findings and that might even lead to the mathematical foundations of widgets. An
economist may argue that type 2 widgets lead to job loss.</p>

<p>Whose lens does the AI assistant use to examine the facts? That is, whose
interpretation of the facts are we getting in the summary if we do not
explicitly ask it to use a certain persona? My current estimate is that it would
represent a blend of Western academic and corporate bland interpretations. It is
a stance. But it would be unfortunate if we all assumed the same stance. The
economist, the mathematician and the maker of widgets will all, over time,
become the same if they keep using the same LLM to explore ideas.</p>

<div class="inset-image-large with-accent">
  <img src="/writing/img/glasses-tree.png" alt="Close-up through the lens of a pair of glasses, with an out-of-focus tree and sky visible sharply only within the lens, blurred everywhere else." />
  
  <p class="image-caption" style="margin-top: 0.5em; font-size: 0.85em;">Nothing out there resolves until it passes through a lens</p>
  
</div>

<p>I want the perspective that I get when I read a paper through the lens of my
experiences, my understanding of the technical landscape, my previous readings,
my personal biases, failings and preferences, and my taste in problems and
solutions. All these and more end up coloring how I interpret the core ideas in
papers I read and also any incidental information that may be in them. My
interpretation does not exist out there waiting for me to find it. It is formed
by the act of my reading the paper, built from the material in the paper along
with what I bring to it.</p>

<p>By removing the ability to interpret, the summary forces a certain
interpretation on me. But the nuances of my personal lens help make new
connections and spark new ideas. Even bad papers and papers I dislike sometimes
do this. If I were to sacrifice the personal perspective, I would be left at the
mercy of the model’s summary and its interpretation.</p>

<p>To be fair, I might end up liking that interpretation. I might even end up
agreeing with it.<sup id="fnref:caveat-about-llm-generated-text"><a href="#fn:caveat-about-llm-generated-text" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> But that is not the point.
What I lose, or at least impoverish, is my own privileged view of the world. A
view that is privileged <em>to me</em> because it is mine. Perhaps my viewpoint is
uninteresting or unintelligible to you. But you have your own viewpoint.</p>

<h3 id="so-why-do-i-like-reading-papers">So, why do I like reading papers?</h3>

<p>Maybe for some papers, all I need is a summary of its contributions. But when I
read an LLM generated summary of the paper, I would collapse the space of
interpretations into the one that the LLM produces. This collapse is
irrevocable. I will never get back my own interpretation once I have seen the
viewpoint that comes from outside.</p>

<p>Consider, as an analogy, books that are made into movies. If you watch the movie
<em>before</em> reading the book, it is difficult to visualize different faces on the
characters than the ones in the movie. I cannot unsee Anthony Hopkins as
Hannibal Lecter or Javier Bardem as Anton Chigurh.</p>

<p>My objection to the LLM generated summary is not about AI authorship at all. It
applies to any secondary material, including textbooks and surveys, both of
which I read. But LLMs are industrial strength tools that are easy to reach for,
and do not need anyone to have ever read the paper. Human-authored summaries
have authors and schools of thought I can push back against.</p>

<p>Will I keep being the person who has my views if I read only bland pre-digested
text? I read papers because I would like my own interpretation of a paper
<em>before</em> I reach for someone else’s. Or something else’s.</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:caveat-about-llm-generated-text">
      <p>When I read an LLM generated piece, I am still going to interpret it from my perspective. But the source material is already compressed. The raw material for my reading/interpretation is already impoverished. <a href="#fnref:caveat-about-llm-generated-text" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name></name></author><category term="ai-and-society" /><category term="llms" /><summary type="html"><![CDATA[Reading a paper is more than just understanding it. The act of my reading the paper creates my interpretation, a privileged view through my lens constructed for me.]]></summary></entry><entry><title type="html">Thriving in Grad School</title><link href="https://svivek.com//writing/2026-07-13-thriving-in-grad-school.html" rel="alternate" type="text/html" title="Thriving in Grad School" /><published>2026-07-13T00:00:00-06:00</published><updated>2026-07-13T00:00:00-06:00</updated><id>https://svivek.com//writing/thriving-in-grad-school</id><content type="html" xml:base="https://svivek.com//writing/2026-07-13-thriving-in-grad-school.html"><![CDATA[<p style="font-size: smaller;"><i>

This essay is based on a talk I gave a few times to incoming PhD students in
computer science.

</i></p>

<hr />

<p>Graduate school looks like school and college. It has courses, exams, advisors
and professors. The resemblance is only superficial. A PhD treated like school,
or worse, like a job, becomes years of grinding toward grades nobody will care
about, and toward a paycheck that is never the point.</p>

<p>Graduate school is closer to an apprenticeship. It is a supervised practice of
<em>learning to learn</em> and <em>learning to think</em> under uncertainty. It is conducted
with someone who has gone through the process before, alongside others who are
learning the same thing.</p>

<h2 id="apprentices-or-peers">Apprentices or Peers?</h2>

<p>By the time the first year is a few months in, a student builds a strange kind
of intimacy with people they have never actually met. The student encounters the
<a href="https://en.wikipedia.org/wiki/Turing_machine">Turing machine</a>, the <a href="https://en.wikipedia.org/wiki/Von_Neumann_architecture">von Neumann
architecture</a>, the
<a href="https://en.wikipedia.org/wiki/Liskov_substitution_principle">Liskov substitution
principle</a>, LeCun’s
<a href="https://en.wikipedia.org/wiki/Convolutional_neural_network">convolutional
networks</a>,
<a href="https://en.wikipedia.org/wiki/Dijkstra%27s_algorithm">Dijkstra’s algorithm</a>,
the <a href="https://en.wikipedia.org/wiki/Cook%E2%80%93Levin_theorem">Cook-Levin
theorem</a>, Valiant’s
<a href="https://en.wikipedia.org/wiki/Probably_approximately_correct_learning">PAC
framework</a>
and so on. These individuals attached to these tools are encountered often
enough that they stop feeling like citations and start feeling like
acquaintances. The original papers may get read with a reverence undergraduate
work rarely demanded. Once familiarity sets in, the instinct is to read the
accumulated list of names as an entry into a group of peers who did what the
student is about to start doing.</p>

<p>That instinct is wrong.</p>

<p>Peer implies parity. Parity invites comparison. Comparison with Turing is a
contest nobody new to the field can win. It is certainly not encouraging to a
first-year doctoral student.</p>

<p>The list names a different kind of relationship. Nobody becomes Turing’s peer by
enrolling in a PhD program. They become his apprentice, in the same sense that
they are apprenticed to their own advisor: studying how he worked rather than
seeking to match what he achieved. The study should look for how he failed at
something and found his way back to it. Unfortunately, failures hardly ever make
it to papers, and so are hard to learn from. Turing is not a peer. He is a
teacher we happen to have never met. And von Neumann. And Dijkstra. And LeCun.
And the uncredited heroes too.</p>

<p>The people mentioned in this essay are publicly recognized for their
contributions. The average PhD-holder is not. By focusing on the named
individuals and their trajectories, the essay seems to indulge in survivorship
bias. To a certain extent that is unavoidable. One of the points the essay makes
is that we can all learn from the greats, whose careers were not always straight
marches to success. Their failures, and subsequent responses, are as instructive
as their successes. However, we are more likely to be influenced by unnamed
heroes around us, whose successes, failures and responses to failures can be as
instructive as those of the celebrities.</p>

<p>This essay is about idea that resilience is the foundation of a successful
graduate school experience.</p>

<h2 id="the-upside-down-year">The Upside-Down Year</h2>

<p>Nearly everyone arriving in a PhD program has spent their entire academic life
near the top of every class they have taken.<sup id="fnref:jeff-erickson"><a href="#fn:jeff-erickson" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> Within a year,
sometimes within a semester, that often stops being true. Courses get harder.
For the first time, grades are not reliable indicators of effort. At the same
time, the actual research, the thing the classes were supposed to prepare a
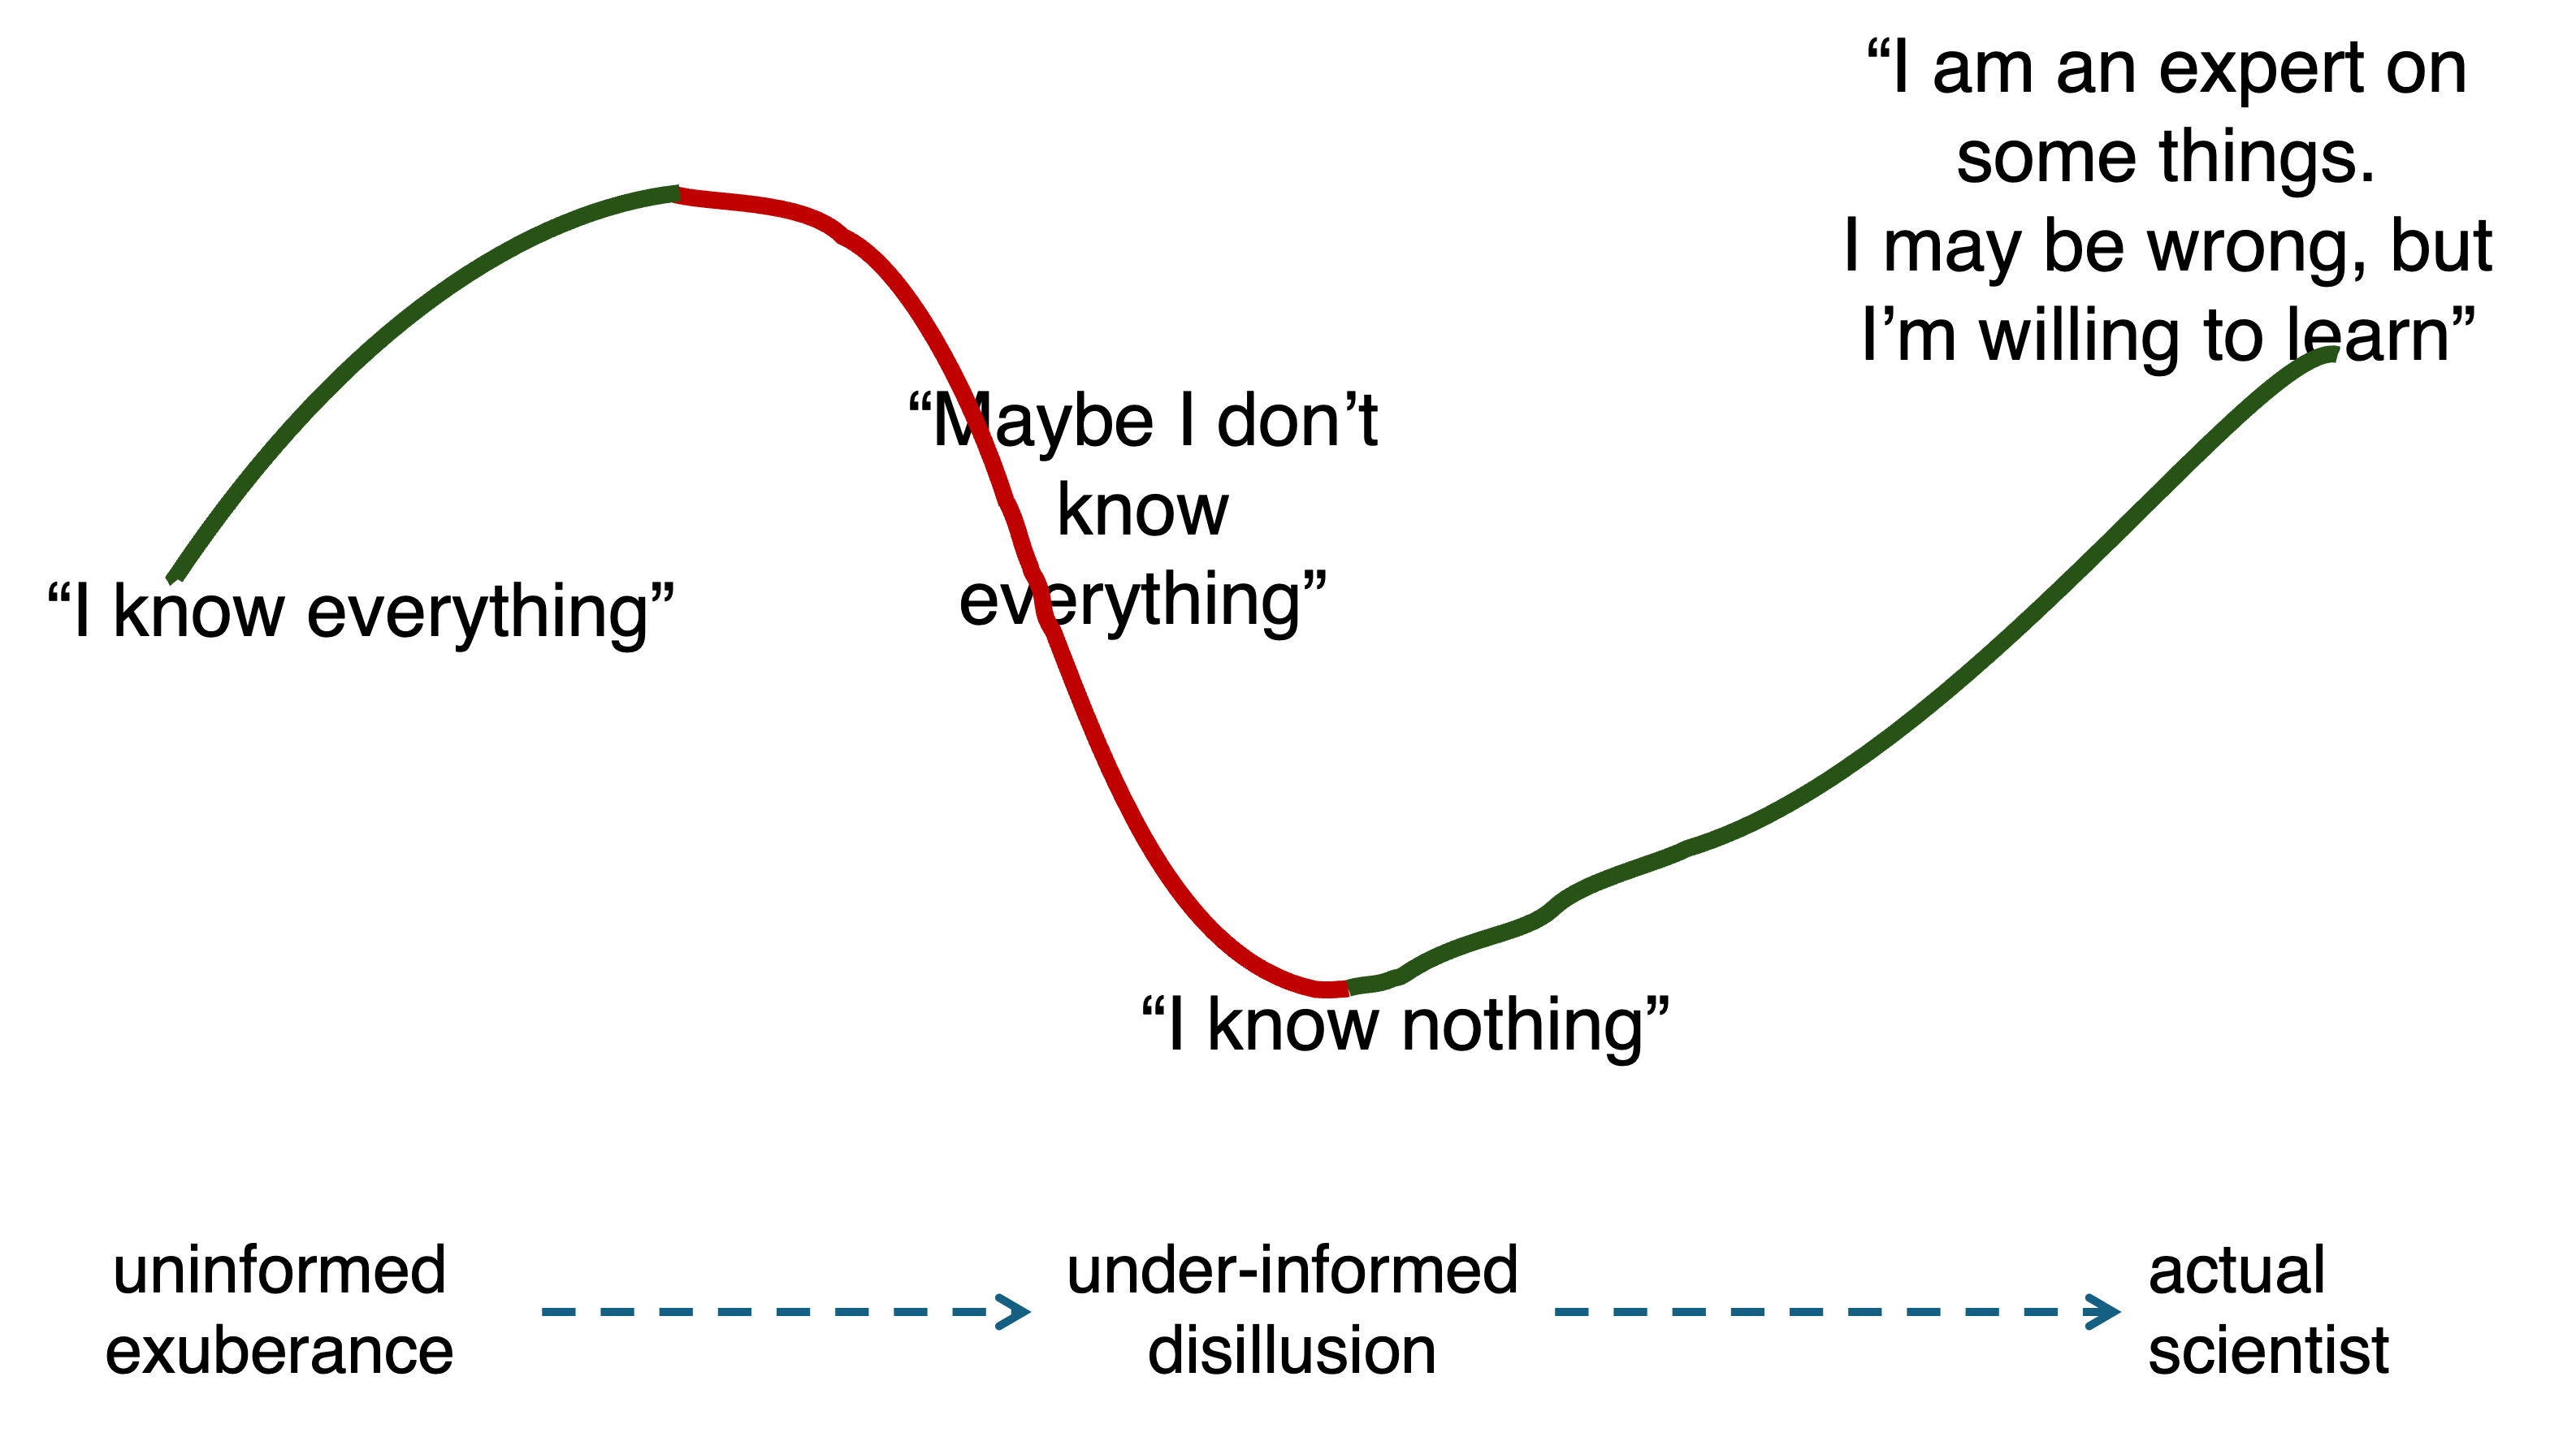
student for, mostly does not work. Two sources of identity collapse. We can call
this phase <em>under-informed disillusion</em>. This is the second of three phases most
students pass through, sitting between the <em>uninformed exuberance</em> of arrival
and the hard-won, durable confidence of an <em>actual scientist</em>.</p>

<div class="inset-image-full with-accent has-light-backdrop">
  <img src="/writing/img/phd-phases.png" alt="A drawing illustrating the phases of a PhD" />
  
  <p class="image-caption" style="margin-top: 0.5em; font-size: 0.85em;">The phases of a PhD</p>
  
</div>

<p>We can picture this journey with a simple plot.<sup id="fnref:man-in-hole"><a href="#fn:man-in-hole" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> Why does the dip
happen? And why does it feel so much worse than it should?</p>

<p>The explanation is that though it may be mistaken for a personal failing, the
dip is the result of a structural asymmetry. Every student in a department can
see everyone else’s successes: the accepted paper, the fellowship, the offhand
mention of something that worked. Almost nobody sees anyone else’s failures,
including their own labmates’. Culturally, failure is private by default and
people choose to only announce success. The asymmetry is sharpest against the
historical greats. Their entire visible record has been curated by decades of
retrospect into a highlight reel. The dead ends are quietly edited out. The
person at the next desk also supplies a milder version of the same asymmetry.
Social media supplies a third version, and it is not mild at all. It is an
endless, worldwide feed of successes: accepted papers, fellowship announcements,
conference photographs and so on. Each post is a small act of self-curation. But
nobody scrolling past has the time to recognize the curation because the next
one arrives. The historical record edits itself slowly, across decades. Social
media edits itself by the hour.</p>

<p>A student weighing their own raw, internally visible struggle against everyone
else’s curated, visible success is running a rigged comparison.</p>

<h2 id="why-pursue-a-doctorate-at-all">Why pursue a doctorate at all?</h2>

<p><em>The right reason to pursue a PhD is the desire to push at the edge of what is
currently known, possible or understood.</em> All the other outcomes of the grad
student experience are byproducts.</p>

<p>Wanting to be one of the names on that opening list is a different motive than
any of those. But it can be a trap. Except for rare instances, the actual work
that matters may involve the patient pursuit of a question nobody yet considers
important. It may even need the willingness to be visibly wrong for years on a
direction the field has not endorsed. While it is happening, this kind of work
may look unproductive and unprestigious. But history might be judge it as
surprisingly impactful. Someone optimizing directly for eventual greatness will
systematically avoid such work in favor of whatever everyone <em>else</em> decides is
impressive. Quite likely, they will never produce it. Wanting to be great as an
end goal is unhealthy, and worse, self-defeating.</p>

<p>For a doctoral student, there is also a timeline problem with chasing visibility
or recognition or greatness directly. Let us look at an example. Judea Pearl’s
foundational work on probabilistic reasoning followed a long temporal arc: the
doctorate came first, the defining contribution years later, the formal
recognition decades after that. It is unlikely that he was optimizing, as a
graduate student, for a recognition that would not arrive within his own
department’s living memory of him as a student. What he was doing, as far as the
record shows, was working on questions he found genuinely unresolved.
Achievement eventually followed.</p>

<h2 id="papers-and-dissertations">Papers and Dissertations</h2>

<p>The end goal of a PhD is a dissertation. Along the way, a student may write
several papers.</p>

<p>A research paper, stripped to its bare bones, contains four things: a problem
that is not yet understood or not yet solved, a question that follows from that
problem, a strategy for approaching the question, and evidence in the form of
results, proofs, experiments, or data.</p>

<p>A thesis asks for a falsifiable claim: that some specific X is novel,
feasible, and useful, or, less often, that X, which the field assumed was
possible, turns out not to be.</p>

<p>There are many false versions of a thesis. “I ran many, many experiments on X”
is not a thesis. “I trained a neural network to do X” is not a thesis. “I worked
for a long time, and it was hard” is not a thesis, even though it happens to be
true of nearly everyone in a graduate program. All three, and many more, share
the same defect: they describe activity. <em>Activity is not achievement.</em></p>

<p>Papers and dissertations are the result of a process, and a sequence of
questions, that is steeped in failure. Rather than describing this in the
abstract, let us see the questions for a concrete idea. Imagine we are working
on a new way to compress a neural network. Is the problem important? Maybe, if
the approach and the neural network itself matter to anyone outside the room. Is
it relevant to what the field cares about? Has the field already found workable
solutions? Suppose the idea survives both questions. Is the idea feasible with
the time and compute available to us? Suppose it is. Do we know what counts as a
correct test for the claim? Is the data available to test the claim something we
can generate or access? Most ideas, including many good ones, die somewhere in
that sequence, often at the first or second question, long before anything
resembling code or an experiment exists.<sup id="fnref:heilmeier"><a href="#fn:heilmeier" class="footnote" rel="footnote" role="doc-noteref">3</a></sup> An idea may also meet the
chopping block because of the vagaries of the peer review system.</p>

<p>The death of an idea is not necessarily failure. Independently rediscovering
something already known in the literature is a success, even if it will not be
published. Finding something too small to matter to anyone else but instructive
to the person who found it is a success. Sometimes the only outcome of a month’s
work is that the process itself got practiced. That too counts, at the level of
a single attempt.</p>

<p>Of course, none of this lowers the bar for the dissertation itself. The
dissertation must be novel, feasible and useful, without exception. The
generosity in the above paragraph belongs to the individual attempts on the way
there, but not to the claims the degree finally rests on.</p>

<p>But where does an idea worth attempting come from?</p>

<h2 id="where-ideas-come-from">Where Ideas Come From</h2>

<p><a href="https://en.wikipedia.org/wiki/T._V._Raman">T. V. Raman</a> did not go looking for
a gap in the literature. He arrived at Cornell seeking a PhD in applied
mathematics. Within his first year, he discovered that listening to mathematics,
rather than seeing it, can be hard. It throws away almost everything the eye
gets for free: the ability to glance ahead, to hold a whole expression in view
while parsing one part of it, to tell immediately whether a fraction’s
denominator is a single term or a sum. Raman is blind. The need to read his own
coursework led to his dissertation titled <a href="https://www.cs.cornell.edu/info/people/raman/phd-thesis/aster-thesis.pdf">Audio System for Technical
Readings</a>.
He <a href="https://awards.acm.org/award_winners/raman_4110221.cfm">won the ACM’s award for the best doctoral dissertation in computing in
1994</a>.</p>

<p>That is about as pure an instance of intrinsic motivation as it gets. But most
students will never have a research question forced on them by something as
urgent. The generalization is that an idea must answer to something real for the
person pursuing it. It does not have to answer to what currently looks
fashionable or to what will read well in a report. Sometimes that realness is a
need as sharp as Raman’s. More often it is just a question that just will not
stop being interesting.</p>

<h2 id="clocking-ideas">Clocking Ideas</h2>

<p><a href="https://en.wikipedia.org/wiki/Alan_Kay">Alan Kay</a>, as a graduate student at
Utah in the late 1960s, saw an early demonstration of flat panel display
technology. Not long after, seeing the <a href="https://en.wikipedia.org/wiki/Logo_(programming_language)">Logo programming
language</a> and
Engelbart’s <a href="https://en.wikipedia.org/wiki/The_Mother_of_All_Demos">Mother of all
Demos</a> left him convinced
that a personal computer the size and weight of a notebook was inevitable. The
hardware to build one did not exist at that time. It would not for
decades.<sup id="fnref:kay-caveat"><a href="#fn:kay-caveat" class="footnote" rel="footnote" role="doc-noteref">4</a></sup> Kay spent much of the rest of his career inventing things
that were needed to realize his conviction, namely a graphical interface and an
object-oriented programming language. Neither of these was the dream itself.
They were the scaffolding the dream needed. The device he had pictured has not
arrived yet. Tablets like the iPad match the form of Kay’s vision. But by his
own account, they fall short in what they allow children to do.</p>

<p>Raman’s idea arrived almost as fast as it could be produced and was recognized
quickly. Pearl’s defining work took a decade to arrive and decades more to be
recognized. Kay’s vision outran the available hardware so badly that he had to
invent intermediate technology just to get partway there. The actual destination
has not yet been reached.</p>

<p>Lined up next to each other, these stories are evidence against the notion that
there is one acceptable shape for where ideas come from, how long it takes for
an idea to take form, or how quickly the world notices it. What stays fixed
across all three is whether the work was real. Activity is still not
achievement, however fast or slow the clock runs.</p>

<h2 id="illusions-of-progress">Illusions of Progress</h2>

<p>Most of what derails a doctorate falls into one of two families.</p>

<p>The first family is avoidance dressed up as virtue. Perfectionism refuses to
ship work because shipping it would expose a claim to the risk of being wrong.
But research requires risk. Waiting for inspiration before starting is the same
avoidance wearing a more sympathetic face. The remedy is to read around the
problem, to talk to people, to simplify, to give a talk describing the
confusion, and to write, even badly or with nothing yet to say. Writing not only
records thinking but also stimulates thinking.</p>

<p>Avoidance can show up disguised as due diligence and spur a student to learn
indefinitely by taking every interesting course on offer and refusing to ever
call the preparation finished. Procrastination and silence travel together:
going quiet when stuck is the cheapest possible way to delay the moment a piece
of work must face anyone’s judgment, including one’s own.</p>

<p>If one family of derailments involves failing to try, the second family is a
failure in judgment about what is worth attempting. Chasing grades optimizes for
a credential future employers or collaborators hardly care about. Also in this
family is scope mismanagement in both of its common forms: wanting to solve
every problem in the world at once means never getting deep enough on any one of
them to say something new, and wanting to solve a problem nobody needs solved
means achieving real depth in something that does not matter. Both failures stem
from never running the idea through the sequence of questions, importance,
relevance, feasibility in the earlier section. The maximalist never reaches
feasibility. The minimalist never reaches importance.</p>

<p>While perfectionism and scope-creep are forms of self-deception, the ultimate
and most fatal derailment is outright deception: misconduct. Everything else on
this list is a person avoiding risk or misjudging what matters. Fabricating a
result, or copying work without citing it, is dishonest. Misconduct is a way for
a person to avoid the risk of being wrong by lying about whether the risk was
taken at all. Misconduct is also a lapse of judgment about the value of honesty.
It is a way of manufacturing a fake success so the real failure underneath it is
never revealed and recovered from.</p>

<h2 id="the-single-practice-underneath-all-of-it">The Single Practice Underneath All of It</h2>

<p>There is a teaching, more associated with meditation than with computer science,
that answers a question almost every beginner asks: how do we get around
constantly losing concentration? The answer given is that losing concentration
is not a failure of the practice. Noticing the loss and returning, without
treating the lapse as a verdict on the person, is the entire practice. The
teaching goes beyond meditation. It is a clear description of the one skill
running underneath everything in this essay.</p>

<p>A stalled experiment on a Thursday afternoon is a small, fast version of that
motion. Notice that the current approach failed, do not treat the failure as a
personal judgment, and return to the problem. The three-phase arc of an entire
doctorate, i.e., exuberance-disillusionment-scientist, is the same motion
stretched across years instead of an afternoon. A career that does not pay off
until long after the degree is the same motion again, run at a scale that
outlasts a single advisor relationship. These are not different skills practiced
at different moments. They are the same skill, practiced at different clock
speeds.<sup id="fnref:notice-and-return-caveat"><a href="#fn:notice-and-return-caveat" class="footnote" rel="footnote" role="doc-noteref">5</a></sup></p>

<p>Seen this way, the usual advice for being a good graduate student stops being a
list of separate virtues and becomes a set of frequent repetitions of that one
skill. Writing daily, even when there is nothing yet worth saying, is a
low-stakes move of exposing a half-formed thought to scrutiny without judgment.
Presenting work while it is still confused, in a group meeting or at a workshop,
is the same practice with an audience attached. Capturing an idea the moment it
appears, before the person who had it talks themselves out of its merit,
protects a fragile attempt long enough for it to be tested properly later.
Mastering the actual tools of the trade, such as the proof techniques, the
experimental protocols, version control, typesetting and so on are easy gains in
the practice.</p>

<p>None of this needs to stay confined to research itself. What happens outside of
research is important. We live in a messy world with deadlines, visas, funding
cliffs, political turmoil, families that measure success differently from what
this essay describes, partners with their own careers and so on. There are no
easy answers on that front. This essay does not address such questions about
life and survival. But, when those are stable and the student has the luxury to
fail well, can external factors help sustain a creative practice?</p>

<p>Outside interests like running, climbing, bridge or golf still earn a place in
the practice for two separate reasons. First, sustained creative attention
depends on more basic needs like rest, health and a life outside the lab. A
doctorate pursued at the expense of everything else does not produce more or
better research. It eventually produces less and worse. The second reason is
more subtle. A misplayed bridge hand, an uncomfortable hike, a round of golf
gone wrong, or a tiring run delivers the same notice-and-return motion described
above. But nobody shows up at a bridge game intending to practice failing. It
does not feel like practice. It feels like Saturday, which may be why it works.
A discipline that announces itself as a discipline is begging to be skipped. One
disguised as fun rarely gets skipped at all.</p>

<p>The advisor relationship is where this entire practice gets watched in person
rather than inferred from an essay like this or a list. An advisor provides
mentorship and funding; in return, a student provides hard work and a genuine
attempt at research, and the doctorate that results belongs to the student, not
to the advisor who supervised it. What passes between the two of them, more than
any specific piece of guidance, is the chance to watch someone further along
fail at something, in real time, and return to it without
flinching.<sup id="fnref:bad-advisors"><a href="#fn:bad-advisors" class="footnote" rel="footnote" role="doc-noteref">6</a></sup></p>

<p>This is apprenticeship made literal. It is a disposition demonstrated up close,
often weekly, until it becomes available to copy.</p>

<h2 id="thriving-in-grad-school">Thriving in Grad School?</h2>

<p>That is the title of this essay. The word “thriving” should sound slightly
wrong. It suggests an arriving to a stable condition and then remaining there,
the way a plant thrives once it finally has enough light and water. Nothing
described here works that way. What gets practiced and watched closely is never
a destination. It is noticing a failure, returning to it without treating the
failure as a verdict, and doing that again. This happens at multiple scales: at
the scale of an afternoon, a PhD and an entire career, alongside people, some
down the hall and some dead for decades, doing the same thing.</p>

<p>A better title would drop the promise of arrival altogether. A better title of
this essay is <strong>An Apprenticeship in Failing Well</strong>.</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:jeff-erickson">
      <p>There are very rare exceptions. <a href="https://jeffe.cs.illinois.edu/">Jeff
Erickson</a> has written about <a href="https://jeffgerickson.substack.com/p/re-phd-with-low-gpa">his undergrad
GPA being low</a>. <a href="#fnref:jeff-erickson" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:man-in-hole">
      <p>This simplistic picture is inspired by <a href="https://www.youtube.com/watch?v=oP3c1h8v2ZQ">Kurt Vonnegut’s wonderful lecture
on the shapes of stories</a>
(Youtube link). The specific shape here is the first one that Vonnegut talks
about: Man in Hole. <a href="#fnref:man-in-hole" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:heilmeier">
      <p>The <a href="https://www.darpa.mil/about/heilmeier-catechism">Heilmeier
Catechism</a> represents the
more thorough vetting of proposals. <a href="#fnref:heilmeier" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:kay-caveat">
      <p>The exact sequence of demonstrations that produced the conviction
has been told a few different ways over the years, including by Kay himself,
so the specific details should be taken as a good story rather than a
settled one. <a href="#fnref:kay-caveat" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:notice-and-return-caveat">
      <p>The notice-and-return practice can help with
failures that originate in the work (such as experiments not working and
unclear next steps) but not with failures imposed from outside (such as
institutional dysfunction and resource issues). The latter class of failures
are outside this essay’s scope and need practical problem solving or
escalation. <a href="#fnref:notice-and-return-caveat" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:bad-advisors">
      <p>This paragraph describes an advisor-advisee relationship that
is functioning well. Not all do. There is a power asymmetry in the
relationship. Moreover, a missed deadline or a failed project usually has
less impact on the advisor than the student. Students with dysfunctional
advisor relationships should seek mentorship elsewhere. Senior students,
other faculty and even members of the broader research community could help.
The apprenticeship model still holds in this situation, but not with the
advisor. <a href="#fnref:bad-advisors" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name></name></author><category term="advice" /><category term="grad-school" /><summary type="html"><![CDATA[Advice for incoming PhD students in computer science about resilience, the hidden struggles of research and the illusions of progress.]]></summary></entry><entry><title type="html">Named Neurons</title><link href="https://svivek.com//writing/2026-01-28-named-neurons.html" rel="alternate" type="text/html" title="Named Neurons" /><published>2026-01-28T00:00:00-07:00</published><updated>2026-01-28T00:00:00-07:00</updated><id>https://svivek.com//writing/named-neurons</id><content type="html" xml:base="https://svivek.com//writing/2026-01-28-named-neurons.html"><![CDATA[<p>In our 2019 paper on augmenting neural networks with logic <a class="citation" href="#li2019augmenting">(Li &amp; Srikumar, 2019)</a>, <a href="https://users.cs.utah.edu/~tli/">Tao Li</a>, and I wrote
about something called a <strong>named neuron</strong>. We introduced it as a concept that
helped bind a symbol in first-order logic to an element of a neural network.
Essentially, named neurons are symbols in neural networks. Over the years, I
have found myself thinking about the idea often, and discussed them most
recently in my <a href="https://svivek.com/teaching/neurosymbolic-modeling">neurosymbolic modeling
class</a>.</p>

<p>I am writing this note to elaborate on the idea. To get things started, we will
look at what a representation is. Then we will look at symbols and neurons,
focusing on how they both derive aspects of their meaning because of the
computation they admit. Finally, we will see what all this has to do with named
neurons.</p>

<h2 id="what-is-a-representation">What is a representation?</h2>

<p>A representation is simply a mapping from one conceptual domain to another. In
this relationship, one domain “stands in” for the other. Let us see some
examples.</p>

<div class="inset-image-full with-accent has-light-backdrop">
  <img src="/writing/img/babylonian-map.png" alt="A Babylonian stone tablet in the center, with a drawing of its content on the left and a map of ancient Babylon represented by the tablet on the right" />
  
  <p class="image-caption" style="margin-top: 0.5em; font-size: 0.85em;">An ancient map. Images courtesy Wikipedia</p>
  
</div>

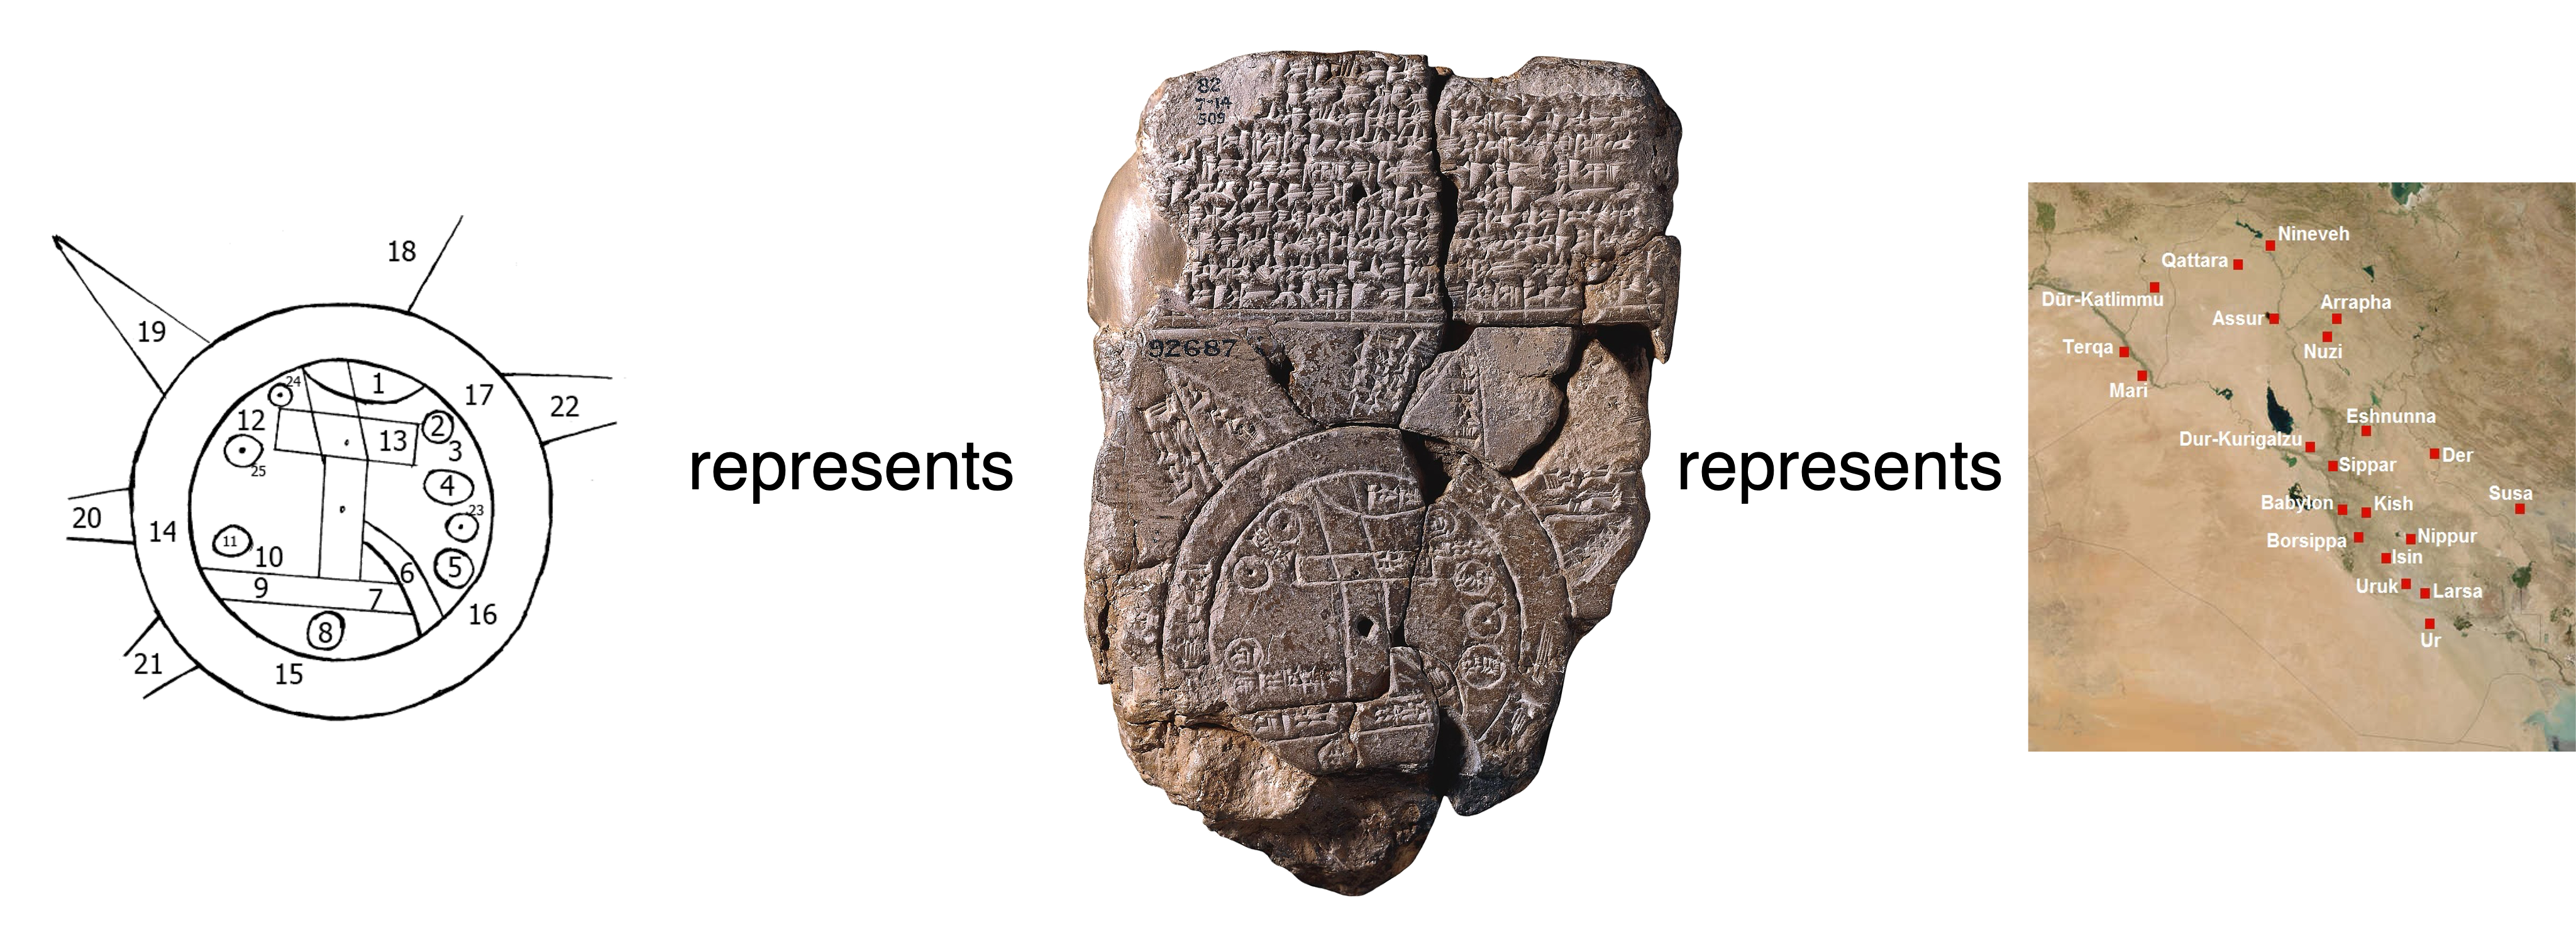
<p>A map is a representation of a territory. Every region in a map corresponds to
some region in a territory. For example, consider this image of <a href="https://en.wikipedia.org/wiki/Babylonian_Map_of_the_World">an ancient
Neo-Babylonian stone tablet supposedly representing the
world</a>
above.<sup id="fnref:wikipedia-ack"><a href="#fn:wikipedia-ack" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> The stone tablet in the middle is an ancient map that
does not follow modern conventions of map design. Wikipedia has a helpful
diagram (shown left) that highlights the key information on the tablet. The
diagram represents the tablet which in turn represents a territory (on the
right). A map of a map, a representation of a representation!<sup id="fnref:nitpick"><a href="#fn:nitpick" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p>Sometimes a representation is built of names or symbols: elements of a (possibly
infinite) discrete set. Emojis are fantastic examples of symbolic
representations that convey <em>prefabricated</em> thoughts. For example, the symbol ⚠️
represents the idea of “warning” and ♀️represents the concept of “femininity” or
“womanhood”. Words and phrases like <code class="language-plaintext highlighter-rouge">curiosity</code>, <code class="language-plaintext highlighter-rouge">transformer neural network</code>
and <code class="language-plaintext highlighter-rouge">Emmy Noether</code> also refer to concepts that may be well-defined or vague.</p>

<p>Such names of concepts are useful because we can use them as prepackaged units
to talk to others. Moreover, such names also relate to one other. For example,
it is probably safe to say that the concepts of <code class="language-plaintext highlighter-rouge">cat</code> and <code class="language-plaintext highlighter-rouge">dog</code> are mutually
exclusive.</p>

<h2 id="what-do-symbols-mean">What do symbols mean?</h2>

<p>Symbolic logic is a language of symbol compositions. There are many families of
symbolic logic; let us take an informal look at first-order logic here.<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">3</a></sup>
First-order logic has several different types of symbols, summarized in the
table below.</p>

<table>
  <tbody>
    <tr>
      <td><em>Constants</em></td>
      <td>Refer to objects and concepts. They could be real or imaginary, and concrete or abstract</td>
      <td><code class="language-plaintext highlighter-rouge">Salt Lake City</code>, $\pi$, <code class="language-plaintext highlighter-rouge">Emmy Noether</code>, ⚠️, ♀️, <code class="language-plaintext highlighter-rouge">curiosity</code>, <code class="language-plaintext highlighter-rouge">transformer neural network</code>, <code class="language-plaintext highlighter-rouge">Exit 213</code></td>
    </tr>
    <tr>
      <td><em>Predicates</em></td>
      <td>State relationships between objects that could either be <code class="language-plaintext highlighter-rouge">true</code> or <code class="language-plaintext highlighter-rouge">false</code></td>
      <td><code class="language-plaintext highlighter-rouge">IsHappy</code>, <code class="language-plaintext highlighter-rouge">IsTall</code>, <code class="language-plaintext highlighter-rouge">BrotherOf</code></td>
    </tr>
    <tr>
      <td><em>Functions</em></td>
      <td>Relate objects to each other</td>
      <td><code class="language-plaintext highlighter-rouge">NextIntegerOf</code>, <code class="language-plaintext highlighter-rouge">RightEyeOf</code></td>
    </tr>
  </tbody>
</table>

<p>Using such symbols, we can write down claims like:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">IsTall(John)</code>: “John is tall”, which may or may not hold.</li>
  <li><code class="language-plaintext highlighter-rouge">IsEven(4)</code>: “The number 4 is even”, which is <code class="language-plaintext highlighter-rouge">true</code>.</li>
  <li><code class="language-plaintext highlighter-rouge">IsEven(NextIntegerOf(4))</code>: “The integer that follows 4 is even”, which is
<code class="language-plaintext highlighter-rouge">false</code> .</li>
</ul>

<p>The language also includes the standard Boolean operators ($\wedge, \vee, \neg,
\rightarrow, \leftrightarrow$) and the universal and existential quantifiers
$\forall, \exists$ respectively. With these operators, we can compose statements
like:</p>

\[\forall x \in \mathbb{Z}, \texttt{IsEven(c)} \rightarrow \neg\texttt{IsEven(NextIntegerOf(x))}\]

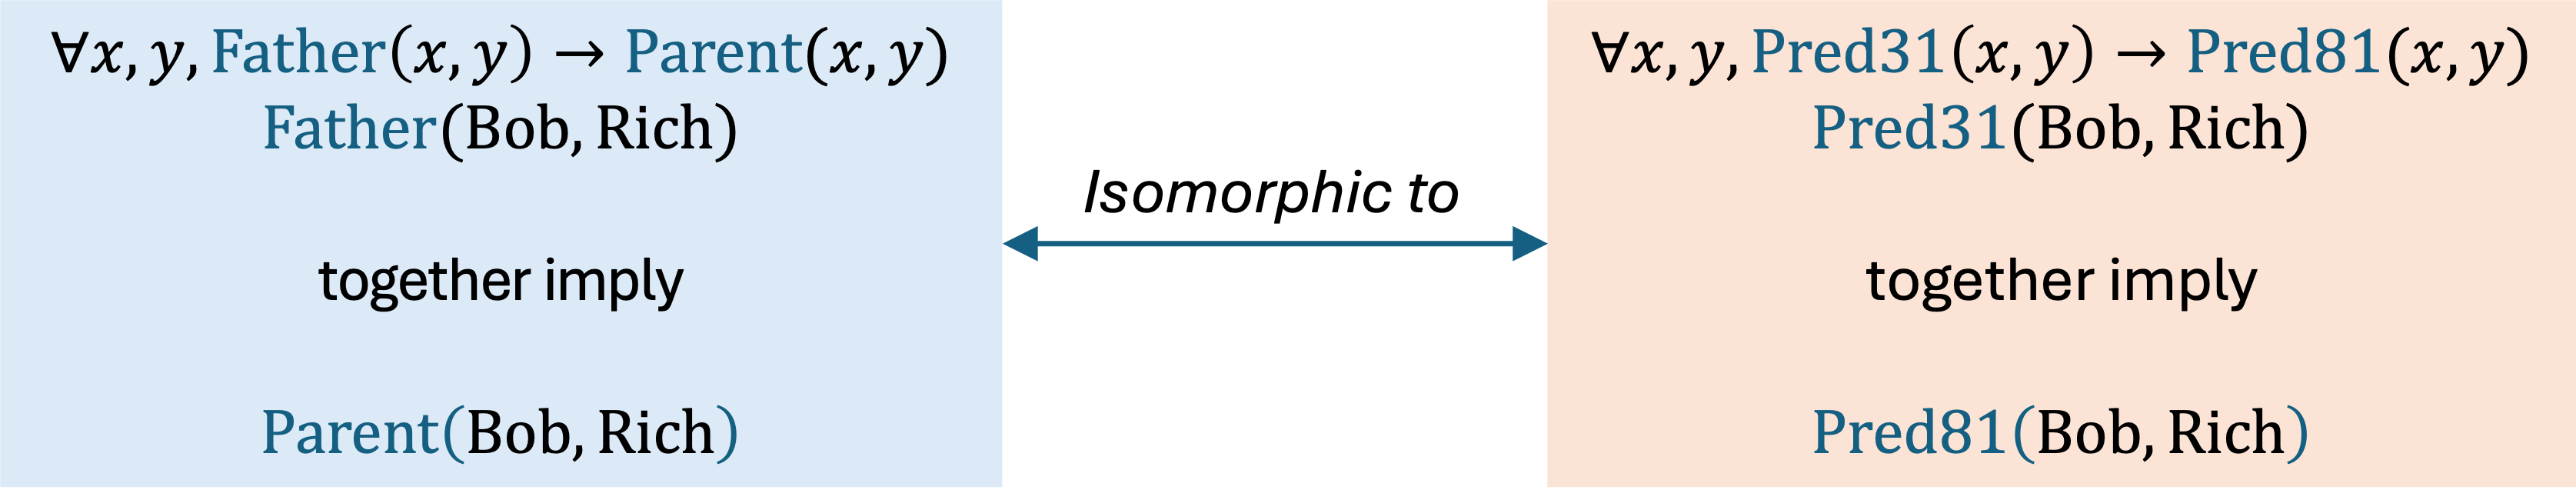
<p>Using a rule like $\forall$ <code class="language-plaintext highlighter-rouge">x</code>, <code class="language-plaintext highlighter-rouge">Father(x, y)</code>$\to$ <code class="language-plaintext highlighter-rouge">Parent(x,y)</code> and the
observation <code class="language-plaintext highlighter-rouge">Father(Bob, Rich)</code>, we can conclude that <code class="language-plaintext highlighter-rouge">Parent(Bob, Rich)</code>. This
is an application of an inference rule.</p>

<p>But do the symbols <em>by themselves</em> have any meaning? That is, what do <code class="language-plaintext highlighter-rouge">IsEven</code>,
<code class="language-plaintext highlighter-rouge">transformer neural networks</code> and <code class="language-plaintext highlighter-rouge">IsTall</code> mean? They look like English phrases,
which is helpful for communication. But the machinery of inference does not
depend on the meaning and choice of the symbols. We could systematically rename
all the symbols and the computational steps of inference would not change.</p>

<p>For example, if we rename <code class="language-plaintext highlighter-rouge">Father</code> and <code class="language-plaintext highlighter-rouge">Parent</code> as <code class="language-plaintext highlighter-rouge">Pred31</code>and <code class="language-plaintext highlighter-rouge">Pred81</code>
respectively, but keep the names of the people as is, we would arrive at the
conclusion <code class="language-plaintext highlighter-rouge">Pred81(Bob, Rich)</code>. This predicate is uninterpretable, and
practically anonymous. What we have done here is similar to renaming variables
in a program: refactoring correctly should not change the behavior of a program.</p>

<div class="inset-image-full with-accent">
  <img src="/writing/img/rule-renaming-isomorphism.png" alt="An illustration that shows that renaming symbols systematically does not change the computational process of inference" />
  
  <p class="image-caption" style="margin-top: 0.5em; font-size: 0.85em;">Renaming the predicate symbols produces a symbolic system that is isomorphic to the original one in terms of the computations that occur with them.</p>
  
</div>

<p>To a certain extent, this is a strength of symbolic reasoning. The process of
inference does not need to know what the symbols mean. By merely manipulating
symbols, we can arrive at valid conclusions without having any clue about what
the symbols mean, or even if they mean anything at all. Systematic renaming of
symbols will not change how they participate in computation, or what computation
can be performed on them.</p>

<p>To summarize this part, there are two aspects to the meaning of a symbol:</p>

<ol>
  <li><em>Meaning from name</em>: What it intrinsically means according to conventional
understanding allows us to communicate symbols with each other. For example,
when I write <code class="language-plaintext highlighter-rouge">RightEyeOf</code>, (I hope) I do not need to explain what that means.</li>
  <li><em>Meaning from computation</em>: What we can do with it, which does not depend on
any intrinsic meaning of the symbols themselves. Symbols could be a private
language if all we need to do is to perform operations on them.</li>
</ol>

<h2 id="do-neurons-mean-anything">Do neurons mean anything?</h2>

<p>Modern neural networks, particularly transformer-type models, are essentially
units of <em>anonymous compute</em>. They are vast computation graphs where internal
nodes do not require intrinsic meaning to function. We can associate meaning
with some elements of a network, usually at the edges. Let us look at two
examples.</p>

<p>Suppose we use BERT to classify whether a sentence is <em>imperative</em> or
<em>interrogative</em>. These labels have meanings defined by an external label
ontology that is outside the model. The inner nodes of BERT, however, are
“homeless” in terms of a semantic home. They are simply numbers in tensors that
are influenced by data and not directly defined in terms of the linguistic
concepts they help process.</p>

<p>Another example is the classic MNIST digit classification task. In a CNN trained
on the task, the input is an image and the output consists of ten nodes,
together the output of a softmax. Each output node is explicitly grounded to a
digit from zero to nine. The outputs are clearly “named”. But what about all the
activations in the layers between the inputs and the outputs?</p>

<p>There is, of course, work that shows that certain concepts can be discovered in
neural networks. An early example is the “cat face neuron” in a trained
convolutional neural network <a class="citation" href="#le2012building">(Le et al., 2012)</a>. But these were accidents
of training, and not the result of intentional design. That is, nobody
designated a certain neuron to be the cat face neuron when the network
architecture was designed. The designation was a <em>post hoc</em> imposition by an
observer.</p>

<p>Sometimes, inner nodes are designated to bear meaning. A good example is the
decomposable attention network <a class="citation" href="#parikh2016decomposable">(Parikh et al., 2016)</a>, an early
neural network for textual entailment. Given a premise and a hypothesis, the
network first encoded the words in both, aligned them using attention and used
the alignment to generate a representation that led to the final entailment
decision. The metaphor was that attention equals alignment. Nodes inside the
network, trained end-to-end, represented soft versions of
alignment.<sup id="fnref:alignment-caveat"><a href="#fn:alignment-caveat" class="footnote" rel="footnote" role="doc-noteref">4</a></sup></p>

<p>There are attempts to discover symbols inside neural networks by projecting them
into high-dimensional spaces. Embeddings are distributed representations that
pack multiple concepts into a single vector. Mechanistic interpretability
techniques seek to disentangle these using tools like sparse autoencoders <a class="citation" href="#huben2024sparse">(Huben et al., 2024)</a>. To state this differently, mechanistic interpretability
attempts to discover symbols or concepts inside neural networks.</p>

<p>What we have, one way or another, is a mapping from elements of neural networks
(inputs, labels, inner nodes, or projections) to external concepts.</p>

<p>The interesting thing is that if you rearrange the matrices in the network, it
is possible to reorganize the network so that the behavior does not change. But
the internal structure is completely different. Nodes in computation graphs do
not care about their specific “address” within the layer. That is, meaning is
not bound to location but to computation. Swapping rows in a matrix produces a
different matrix, but if subsequent computations account for that swap, the
overall behavior remains unchanged.</p>

<p>So the lesson is that meaning in neural networks is bestowed in two ways: by
tying elements to external concepts, and by the computational processes that
operate on them. The meaning of a cat neuron is not intrinsic; it could have
appeared elsewhere if the matrices were shuffled.</p>

<p>Once again, just like symbolic logic, meaning is a function of computation.</p>

<h2 id="what-are-named-neurons">What are named neurons?</h2>

<p>We have seen that both symbols and neurons acquire aspects of their meaning by
the computation they admit. Symbols may have intrinsic (human-understandable)
meaning by the choice of their name, and they are assigned meaning via mappings
to external concepts. The name assigned to a symbol allows us to communicate
about the system and constrain it. Can we similarly assign names to neurons?</p>

<p>In our 2019 paper, we said a named neuron is an element of a neural network that
has external semantics. More precisely, it is a neuron that admits a mapping to
a symbolic space.</p>

<p>Formally, a named neuron is a <em>scalar</em> activation in a neural network that
admits a mapping to a symbol in a formal system, enabling logical reasoning over
the network.</p>

<p>If a representation is a mapping from one domain to another, then a named neuron
is a bridge that closes the gap between the discrete world of symbols and the
continuous world consisting of tensors.</p>

<div class="inset-image-large with-accent has-light-backdrop">
  <img src="/writing/img/named-neuron.png" alt="A three-way mapping of symbols, computation graph nodes and concepts" />
  
  <p class="image-caption" style="margin-top: 0.5em; font-size: 0.85em;">A three-way mapping of symbols, computation graph nodes and concepts</p>
  
</div>

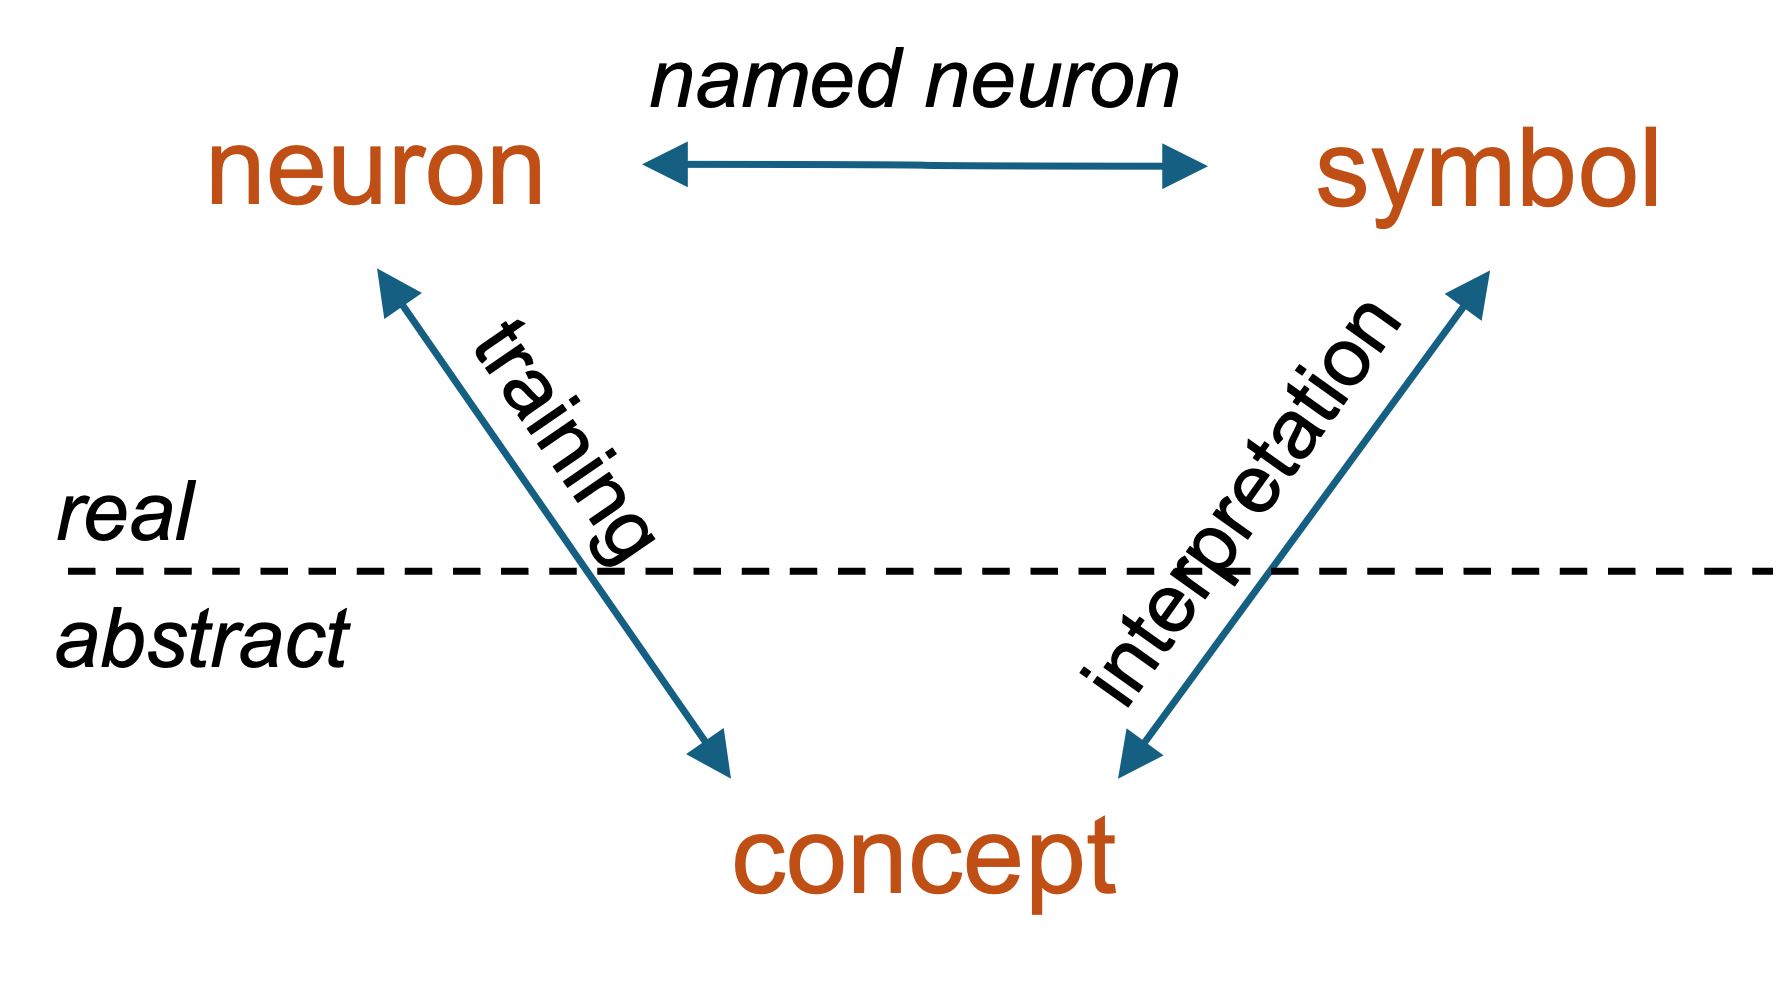
<p>We can think of this as a three-way mapping. Symbols map to concepts through
interpretations. Some nodes in neural networks map to concepts. We argue for a
mapping between symbols and neural network nodes via named neurons.</p>

<p>In other words, while a neural network may be awash with anonymous units of
compute, named neurons are some nodes in the network which may be recognizable
as concepts.</p>

<p>Now we have a complete picture. Consider the BERT example again. The output node
labeled <em>imperative</em> is a symbol. In fact, it is a predicate. Outputs of neural
networks are predicates. Inputs are objects. This gives us a first-order logic
mapping. When a neural network predicts that a sentence <code class="language-plaintext highlighter-rouge">x</code> is an imperative, we
can think of it as asserting the truth of a proposition <code class="language-plaintext highlighter-rouge">Imperative(x)</code>.</p>

<p>Inner nodes may also be predicates. For example, if the output node
corresponding to a <em>cat</em> label corresponds to the predicate <code class="language-plaintext highlighter-rouge">IsCat(x)</code> for an
input image <code class="language-plaintext highlighter-rouge">x</code>, then the “cat-face” neuron in the CNN might represent a
predicate called <code class="language-plaintext highlighter-rouge">HasCatFace(x)</code>.</p>

<p>How do we find named neurons in practice? Sometimes they are designed in (output
labels and even nodes in hidden layers, though not always), sometimes discovered
post-hoc (cat face neurons), or extracted systematically through mechanistic
interpretability techniques like sparse autoencoders. The field is moving from
accidental discovery to principled extraction.</p>

<h2 id="what-does-naming-neuron-give-us">What does naming neuron give us?</h2>

<p>Why bother naming neurons? Why not let the “distributed representation” handle
everything in its high-dimensional, anonymous way?</p>

<p>Naming a neuron transforms it from a passive statistical artifact to an active
participant in reasoning. Doing so opens the doors to new ways to think about
neural networks.</p>

<p>First, we could write logical rules that constrain a network’s behavior despite
what it learns during training. For example, we could have a rule that says
“do not predict cat if a cat face is no recognizable”, written as:</p>

\[\neg\texttt{HasCatFace(x)} \to \neg \texttt{IsCat(x)}\]

<p>We could enforce this rule at test time at the cost of extra compute for
verification to get a more robust predictor.</p>

<p>Second, we could define loss functions that encourage rule-following behavior.
This way, we would not need to apply the rule at test time. This approach
promises ways for our models to do better than the data they are trained on.</p>

<p>Finally, named neurons could help enhance interpretability. Techniques like
sparse autoencoders are essentially “naming machines”. They attempt to find
latent symbols buried in the anonymous vectors by projecting them into a new
space that disentangles concepts. We could even close the loop from
interpretability to model improvement with constraints.</p>

<p>By naming a neuron, we give it a role in a larger story, one governed by the
laws of logic, not just the randomness of gradient descent.</p>

<p>In future posts, we will explore how named neurons enable new training
objectives and architectural choices. For now, the key insight is that by naming
neurons, we gain leverage, namely the ability to reason about and constrain what
neural networks do.</p>

<h2 id="references">References</h2>

<ol class="bibliography"><li><span id="li2019augmenting">Li, T., &amp; Srikumar, V. (2019). Augmenting Neural Networks with First-order Logic. <i>Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics</i>, 292–302.</span></li>
<li><span id="russell2021artificial">Russell, S. J., &amp; Norvig, P. (2021). <i>Artificial Intelligence: A Modern Approach</i> (Fourth Edition). Pearson.</span></li>
<li><span id="le2012building">Le, Q. V., Ranzato, M. A., Monga, R., Devin, M., Chen, K., Corrado, G. S., Dean, J., &amp; Ng, A. Y. (2012). Building high-level features using large scale unsupervised learning. <i>Proceedings of the 29th International Coference on International Conference on Machine Learning</i>, 507–514.</span></li>
<li><span id="parikh2016decomposable">Parikh, A., Täckström, O., Das, D., &amp; Uszkoreit, J. (2016). A Decomposable Attention Model for Natural Language Inference. <i>Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing</i>.</span></li>
<li><span id="huben2024sparse">Huben, R., Cunningham, H., Smith, L. R., Ewart, A., &amp; Sharkey, L. (2024). Sparse Autoencoders Find Highly Interpretable Features in Language Models. <i>The Twelfth International Conference on Learning Representations</i>.</span></li></ol>

<hr />

<div class="foldable-note">
  <div class="foldable-note-header">
    <h3 class="foldable-note-title">How to cite this post</h3>
    <span class="foldable-note-toggle">▼</span>
  </div>
  <div class="foldable-note-content">
    <div class="foldable-note-inner">
      
<p><strong>Recommended citation:</strong></p>

<p>Srikumar, Vivek. “Named Neurons.” January 27, 2026. https://svivek.com/writing/named-neurons.html</p>

<p><strong>BibTeX:</strong></p>
<div class="language-bibtex highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">@misc</span><span class="p">{</span><span class="nl">srikumar2026named</span><span class="p">,</span>
  <span class="na">author</span> <span class="p">=</span> <span class="s">{Srikumar, Vivek}</span><span class="p">,</span>
  <span class="na">title</span> <span class="p">=</span> <span class="s">{Named Neurons}</span><span class="p">,</span>
  <span class="na">howpublished</span> <span class="p">=</span> <span class="s">{\url{https://svivek.com/writing/named-neurons.html}}</span><span class="p">,</span>
  <span class="na">year</span> <span class="p">=</span> <span class="s">{2026}</span><span class="p">,</span>
  <span class="na">month</span> <span class="p">=</span> <span class="s">{January}</span><span class="p">,</span>
  <span class="na">note</span> <span class="p">=</span> <span class="s">{Blog post}</span>
<span class="p">}</span>
</code></pre></div></div>


    </div>
  </div>
</div>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:wikipedia-ack">
      <p>All three images are courtesy Wikipedia:
[<a href="https://en.wikipedia.org/wiki/Babylonian_Map_of_the_World#/media/File:BabylonianWorldMap2.jpg">1</a>],
[<a href="https://en.wikipedia.org/wiki/Babylonian_Map_of_the_World#/media/File:Baylonianmaps.JPG">2</a>]
and [<a href="https://commons.wikimedia.org/wiki/File:Meso2mil-English.JPG">3</a>] <a href="#fnref:wikipedia-ack" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:nitpick">
      <p>If you want to nitpick, you might observe that even the rightmost
image is a representation because it is just a map, not the actual
territory. So what we have is a map of a map of a map. And if you want to
nitpick more, you might note we have an image, i.e., a representation, of
the stone tablet, not the tablet itself. <a href="#fnref:nitpick" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>If you are interested, Russell and Norvig’s AI book <a class="citation" href="#russell2021artificial">(Russell &amp; Norvig, 2021)</a> has an excellent introduction to logic that
presents this more formally in the context of AI. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:alignment-caveat">
      <p>Of course, not every use of the attention mechanism is
interpretable. Self-attention within transformer networks are not. <a href="#fnref:alignment-caveat" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name></name></author><category term="neuro-symbolic" /><category term="interpretability" /><summary type="html"><![CDATA[This post elaborates on the concept of a named neuron, which bridges neural networks with symbolic logic.]]></summary></entry><entry><title type="html">Five Million Years of Solitude</title><link href="https://svivek.com//writing/2025-11-23-5-million-years-of-solitude.html" rel="alternate" type="text/html" title="Five Million Years of Solitude" /><published>2025-11-23T00:00:00-07:00</published><updated>2025-11-23T00:00:00-07:00</updated><id>https://svivek.com//writing/5-million-years-of-solitude</id><content type="html" xml:base="https://svivek.com//writing/2025-11-23-5-million-years-of-solitude.html"><![CDATA[<div class="inset-image-small with-accent">
  <img src="img/A-kadabba-reading.png" alt="A silhouette of A. kaddaba reading a stack of papers" />
  
</div>

<p>How big is the <a href="https://huggingface.co/spaces/HuggingFaceFW/blogpost-fineweb-v1">FineWeb
corpus</a>? The
documentation tells us that it has 15 trillion tokens, but the number is hard to
picture.</p>

<p>Instead, let’s go back in time to meet the <em><a href="https://en.wikipedia.org/wiki/Ardipithecus_kadabba">Ardipithecus
kadabba</a></em>. It is an early
hominid that lived about 5.7 million years ago, soon after ancestral chimps and
early hominids parted ways from their common ancestral hearth.</p>

<p>Imagine that an A. kadabba decided to start reading the corpus at the pace of a
modern American leisure reader. Busy with her reading, she would have bypassed
the whole Homo erectus, Neanderthal and Denisovan business, missed the birth of
the first Homo sapiens, and would be wrapping up her reading just in time to use
a modern chatbot.</p>

<p>Of course, she would be no match for the chatbot because she has only been
pretrained, and that too largely on 21st century English text. I suspect that
the surprisingly literate and well-read hominid would have been disappointed and
questioning the purpose of having stayed up (and alive) doing all that reading.
She would still need instruction tuning and preference alignment. But still,
they say reading builds character. And character, like personality, goes a long
way.</p>

<p>Maybe the lesson isn’t about how much data we can shovel into the system, but
that we need a better way to structure the intelligence we build.</p>

<div class="foldable-note">
  <div class="foldable-note-header">
    <h3 class="foldable-note-title">Technical details: Why 5.7 million years?</h3>
    <span class="foldable-note-toggle">▼</span>
  </div>
  <div class="foldable-note-content">
    <div class="foldable-note-inner">
      
<p>How did we arrive at the number 5.7 million for the number of years will take to
read the FineWeb corpus? If you’re curious, and don’t mind some aggressive
approximations, read on.</p>

<h3 id="tokens-to-words">Tokens to words</h3>

<p>The FineWeb corpus has 15 trillion tokens. According to <a href="https://huggingface.co/spaces/HuggingFaceFW/blogpost-fineweb-v1">the blogpost describing
the corpus</a>,
the tokens are constructed using the GPT2 tokenizer. The exchange rate between
tokens and words is not 1:1. Words can, and are, broken down into subwords by
the tokenizer. Small words may be retained as is, and bigger words will be
broken down. As of now, <a href="https://help.openai.com/en/articles/4936856-what-are-tokens-and-how-to-count-them">the rule of thumb suggested by
OpenAI</a>
suggests that we can of 100 tokens as 75 words, which gives an exchange rate of
1.33 tokens per word.</p>

<p>But that is for the more recent tokenizer, whose vocabulary size (i.e., the
number of word pieces) is much larger. GPT2’s vocabulary contains about 50,000
tokens. If we make the vocabulary smaller, then more words will not be in it,
and will get broken up. As a result, the number of tokens we get from a word
will be bigger.</p>

<p>Consequently, we can think of one word as 1.5 tokens. With this exchange rate,
the FineWeb corpus will have 10 trillion words.</p>

<h3 id="words-to-books">Words to books</h3>

<p>Now that we have an estimate of how many words are in the corpus, let us now
estimate how many books they can fill up. Of course, we will need to make
aggressive approximations here. Books can be long (Marcel Proust’s <em>In Search of
Lost Time</em> is about 1.2 million words long), and books can be short (Animal Farm
has about 30,000 words.) However, an average book has about 80,000 to 100,000
words. Let us take the upper end for simplicity.</p>

<p>FineWeb has 10 trillion words. At 100,000 words per book, the corpus corresponds
to 100 million books!</p>

<h3 id="books-to-years">Books to years</h3>

<p>Finally, let us see how long it takes to read 100 million books. <a href="https://worldpopulationreview.com/country-rankings/average-books-read-per-year-by-country">According to
the World Population
Review</a>,
an average American reader reads 17 books per year. To read 100 million books,
it will take about 5.88 million years. Conveniently, this is quite close to when
the A. kadabba lived, except for a slight error. Maybe the A. kadabba in our
story is a faster reader, and shaves off 0.18 million years. This gives us the
5.7 million years.</p>


    </div>
  </div>
</div>]]></content><author><name></name></author><category term="humor" /><category term="llms" /><summary type="html"><![CDATA[Suppose an early hominid started reading the FineWeb corpus...]]></summary></entry><entry><title type="html">Welcome</title><link href="https://svivek.com//writing/2025-11-22-welcome.html" rel="alternate" type="text/html" title="Welcome" /><published>2025-11-22T00:00:00-07:00</published><updated>2025-11-22T00:00:00-07:00</updated><id>https://svivek.com//writing/welcome</id><content type="html" xml:base="https://svivek.com//writing/2025-11-22-welcome.html"><![CDATA[<p>Over the years, I have been explaining my research to slightly different
audiences: <a href="/students.html">students</a>, linguists, mental health experts, <a href="https://www.price.utah.edu/ai/upskilling-in-ai">Utah
faculty learning about AI</a>, etc.
Each conversation has been slightly different, but has taught me more about AI.</p>

<p>This blog is an attempt to continue those conversations and working through
ideas publicly. What kinds of ideas? That the most interesting AI challenges are
not just about scale. That techno-solutionism without context from domain
experts may be problematic. You can find more about <a href="/research">my research interests
here</a>. My current research focuses on neuro-symbolic methods,
low-data domains and resources, and systematic benchmarking.</p>

<p><strong>What I’ll write about</strong>: Research ideas. Lecture notes on topics like
<a href="/teaching/neurosymbolic-modeling">neuro-symbolic methods</a>. Thinking about
benchmarking beyond metrics. Thinking about linguistic phenomena. Making AI do
interesting things with limited data or compute resources. Commentary about AI
and society.</p>

<p>But I will likely also write about topics that are not just AI-related. I
generally like nerdy things, sometimes do recreational math for relaxation,
enjoy reading and writing good code, and am almost always reading a book or two
if I can find the time.</p>]]></content><author><name></name></author><category term="meta" /><summary type="html"><![CDATA[Why this blog exists]]></summary></entry></feed>